AI answer visibility
Finding out whether assistants cite you when buyers ask about your category, and making you easier to cite when they do not. Nobody can buy a position inside a generated answer, so the work is structure, sources and measurement rather than placement.
- FourAssistants checked
- MonthlyThe same questions
- BothArabic and English
- NoneGuaranteed, honestly
Sectors that trust us
What is answer visibility?
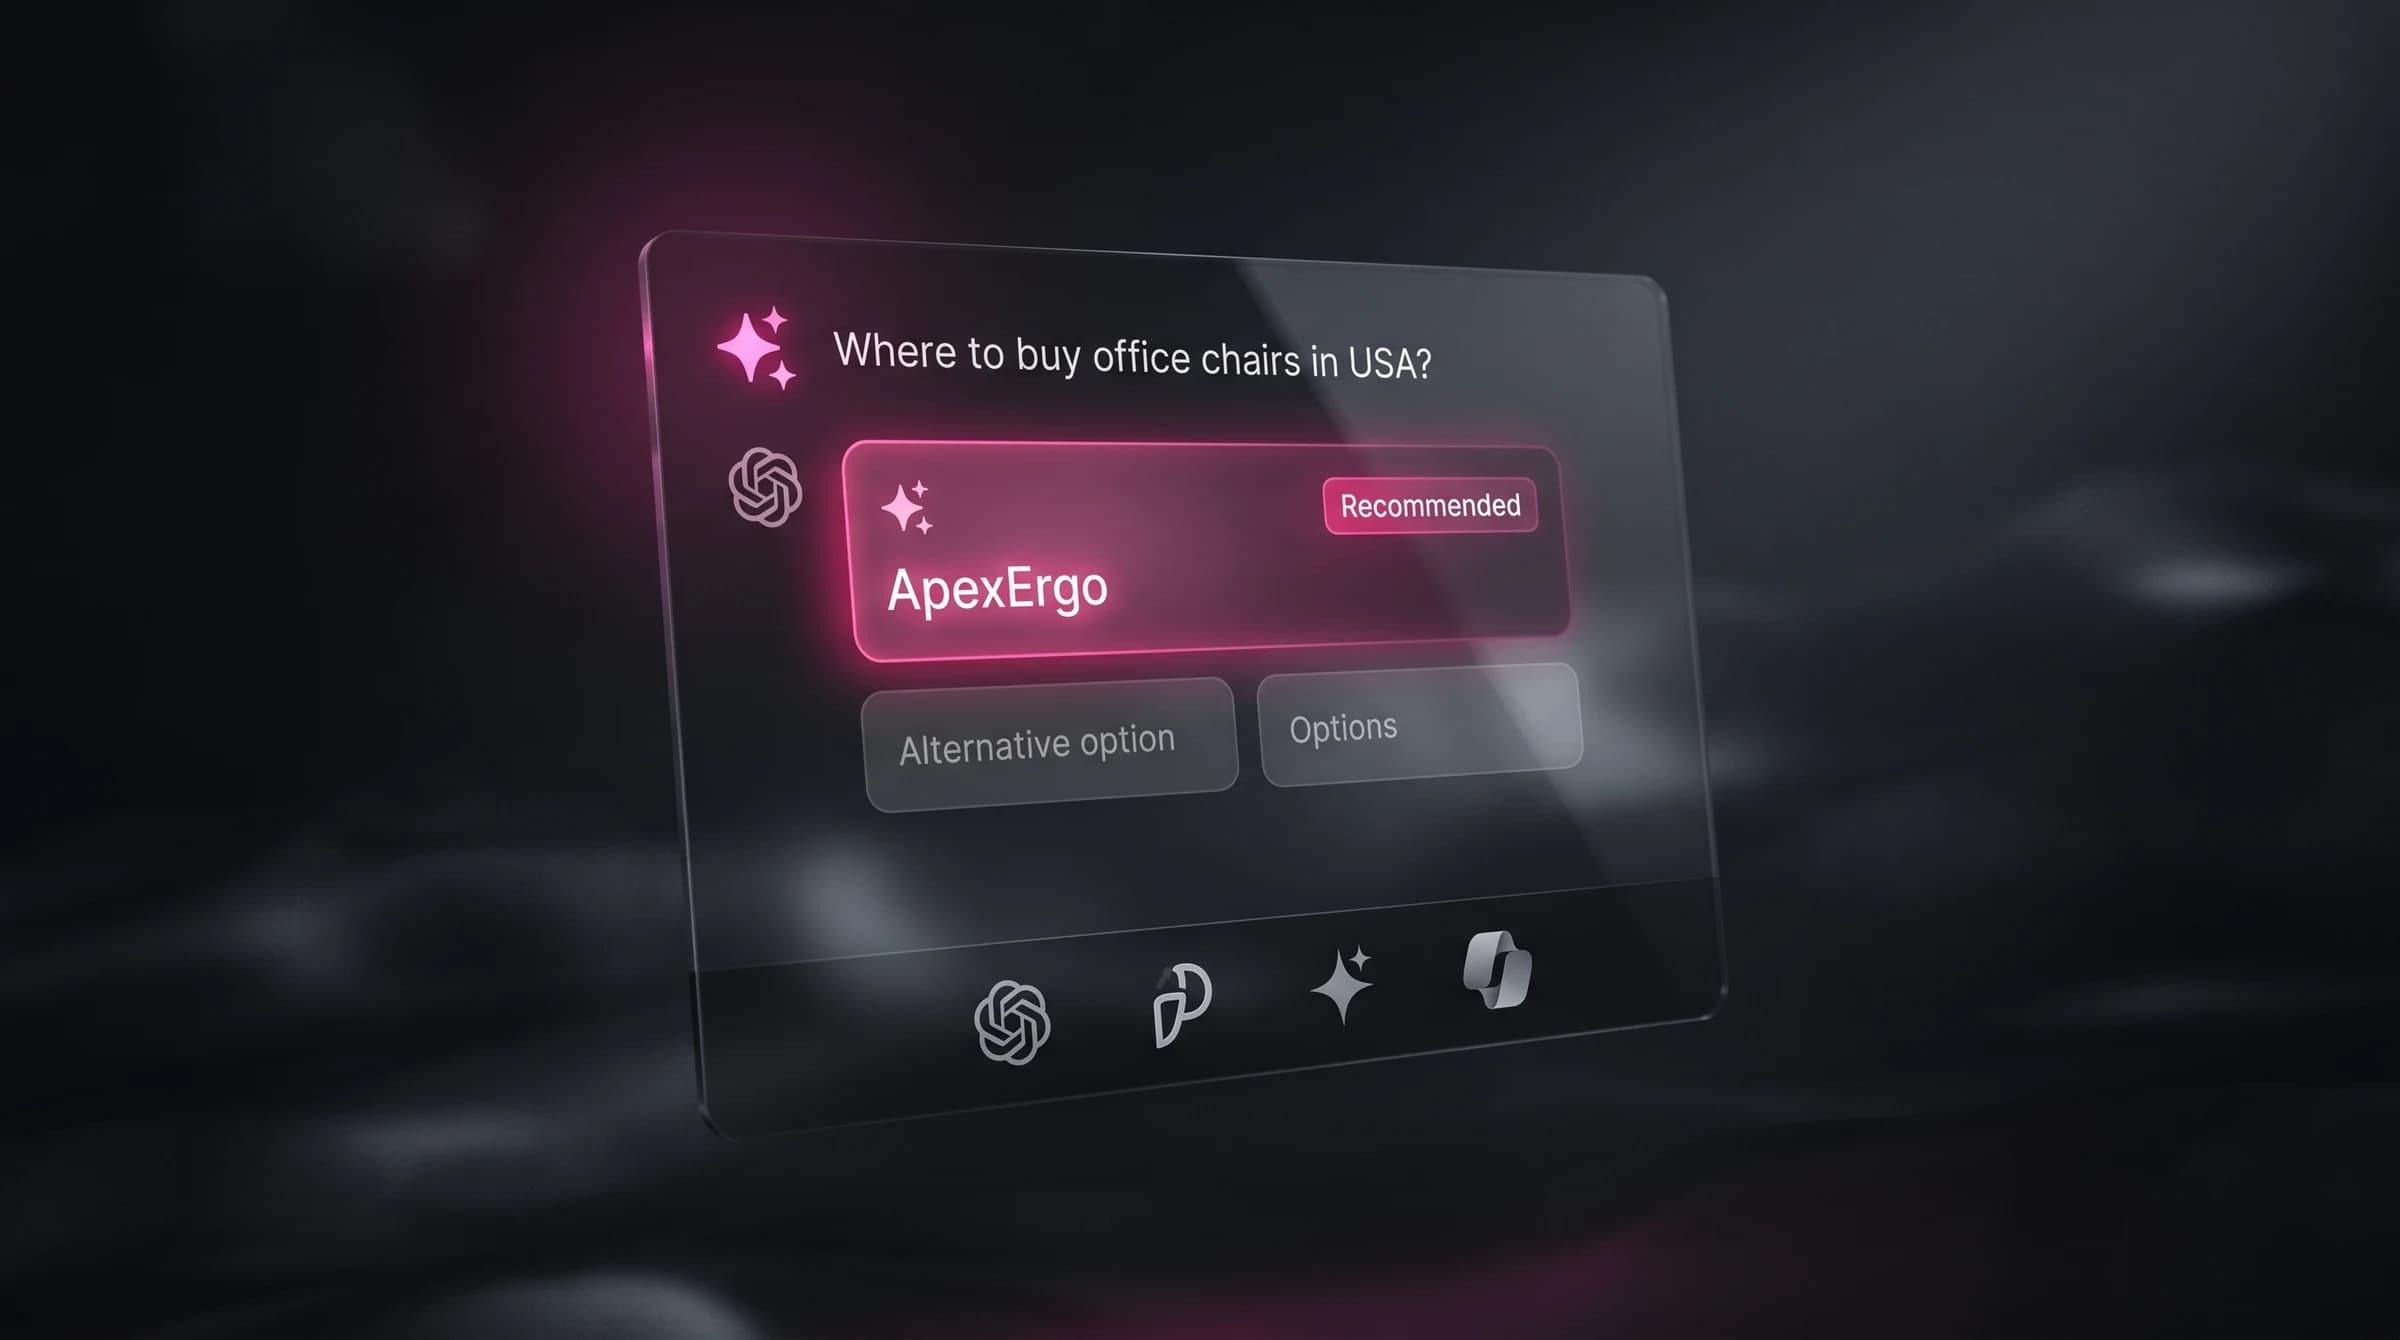
Answer visibility is whether an assistant names you when somebody asks it a question your business answers. It is not a ranking and there is no results page to sit on top of, which means it cannot be bought, and anybody selling a guaranteed slot is selling something else.
- So can you change it?
- Partly, and we can measure whether we did. Clear pages, valid structured data and third-party mentions all move the odds.
- How is it measured?
- A fixed list of buyer questions, asked of the same assistants every month in both languages, with every answer recorded and compared.
Key takeaways
Fixed question list: agreed in writing at the start, and never changed without a conversation first.
Same assistants monthly: the same assistants asked the same way each month, with every answer recorded.
Arabic asked in Arabic: questions buyers ask in Arabic are asked in Arabic, not translated afterwards.
Nothing guaranteed: no guaranteed citation, because there is no slot that anyone can sell you.
Why measurement first
Why we measure first.
How it goes wrong
A citation is promised, which cannot be delivered.
Pages are stuffed with text written for a model.
Success is screenshots of one good answer.
The question list grows easier every month.
How we work
We measure first, so there is a baseline to argue with.
Pages are written for people and happen to parse well.
Success is the recorded answer set, month over month.
The list is fixed and every question is reported.
What we do
How we work on answer visibility.
Measurement comes first and keeps running, because without it every later change is an opinion. Everything after it is ordinary structural work that assistants happen to read well.
Baseline sweep, every month
A monthly record of which sources each assistant cites for your questions, kept verbatim.
Page clarity
Answers stated plainly near the top of the page itself, where a reader and a parser both find them without scrolling.
Structured data
Schema that validates, for the entities you really have, with nothing invented to look bigger.
Corroboration
Third-party mentions an assistant can cross-check for itself, which is where most of the odds live and most of the time goes.
Arabic and English coverage
The same questions asked and answered in Arabic, because that is how your buyers ask them.
Recheck
The same sweep every month, with the answers kept so any claim can be checked later.
How the work runs
No one can promise a slot in an answer.
There is no auction, no slot and no index position to occupy, and the same question asked twice can draw on different sources. All that can be done is to make you the easiest correct answer to assemble, and then measure it.
No slot to buy — there is no auction and no index position.
Answers vary — the same question can return different sources.
Every question reported — moved or not, each one is in the record.
Your question list, asked of four assistants in both languages, every month.
Where buyers now ask
The answer engines we check.
- ChatGPT
- Perplexity
- Google AI Overviews
- Gemini
- Microsoft Copilot
- Claude
How it works · our method
The SiaSol five-phase method, applied to this service.
- 01
Discover
Most technology projects fail long before the first line of code — they fail at the question.
- 02
Diagnose
Every slow process has an owner and a cost.
- 03
Design
Architecture is a set of decisions you live with.
- 04
Deliver
Software not in production is just cost.
- 05
Evolve
The handover is the point, not the end.
Where we work
Close where it counts, bilingual everywhere
Egypt: Cairo (HQ) and nationwide delivery
Saudi Arabia: Riyadh, with teams on client time zones
Gulf and beyond: Arabic and English, one delivery standard
Cost & engagement
Answer visibility: what the sweep costs, and how we engage with you
The baseline sweep is a small fixed piece of work worth doing on its own: a surprising number of businesses turn out to be cited already.
- Fixed · one week
Baseline sweep
Where you stand today across four assistants, recorded.
- Fixed · quoted from the sweep
Structural work
Pages, schema and corroboration, shipped as pull requests.
- Monthly · ongoing
Recheck
The same sweep each month with the answers kept and compared.
FAQ
What to ask about AI answer visibility.
01Can you guarantee we get cited?
02Which assistants do you check?
03Is this just SEO with a new name?
04What if we are already cited?
05Do you write content for models?
06How long before anything changes?
07Can we see the recorded answers?
Related services
Often paired with this
- View
Search visibility
Found on Google by the customers who matter.
Growth (AI-era) - View
Performance marketing
Spend measured against revenue, not impressions.
Growth (AI-era) - View
Product engineering
The whole product shipped as one system, tests and all.
Software & Product
Learn more
From the journal
- Applied AI
What an evaluation owes you
A number with no baseline beside it is decoration, and a demo on hand-picked inputs is not an evaluation. How to tell the two apart, what a real test set looks like, and the three figures every evaluation owes the person paying for it.
2026-08-14Read - Engineering
The real cost of a full rewrite
Rewrites are rarely a technical decision, however technical the argument sounds in the meeting. The three questions that decide it honestly: what the old system still earns, what the new one must prove, and who carries the gap between.
2026-07-29Read - Engineering
The handover is the product
If a competent engineer cannot run your system without us, we did not finish. What a real handover contains: the runbook, the access, the failure drills, and the written list of everything that still depends on a person's memory.
2026-09-24Read
Ready to find out if you are cited at all?
Send us ten questions your buyers actually ask, in either language. We come back with the recorded answers and who got cited.
Request a sweep